
The number one rule for high-quality accessible captioning is readability. After all, if nobody can read your captions, then none of the other rules matter. People put so much effort into adding captions. It’s a shame when they make poor captioning choices that you can’t read them.
The following example shows the problem when captions don’t have a dark background for contrast.

A best practice for captioning live events is to hire an amazing human captioner. A11yNYC has worked with Mirabai Knight from the beginning of doing this Meetup. Mirabai presented on Why Human Captioning? at A11yNYC. She gives details on a lot of the reasons why you can’t rely on automated captions. A lot of the things that Thomas and I talk about in this post illustrate why you can’t rely on an artificial intelligence (AI) solution.
AI Captioning Services Used in the Test Cases
Thomas explains Equal Entry’s captioning project in which we looked at four popular AI captioning services:
The first one is YouTube. When you upload a video to YouTube, you set what language the video is being spoken in. You pick one language, and that will typically create AI-generated captions for the video. You can download those subtitles and work with them. YouTube offers VTT, SRT, and SBV caption file formats.
YouTube does not automatically caption all videos. YouTube provides a list of the reasons a video may not generate automatic captions:
- Still processing complex audio.
- Don’t support video language.
- Video is too long.
- Video contains poor sound quality or YouTube can’t recognize speech.
- Video has long period of silence at the start of the video.
- Video contains multiple speakers overlapping or speaking more than one language.
Another captioning service is Microsoft’s Azure Video Indexer. This is a paid service you can try some of its functionality based on the amount of video content. This model is different from YouTube in that you’re paying for each video you upload.
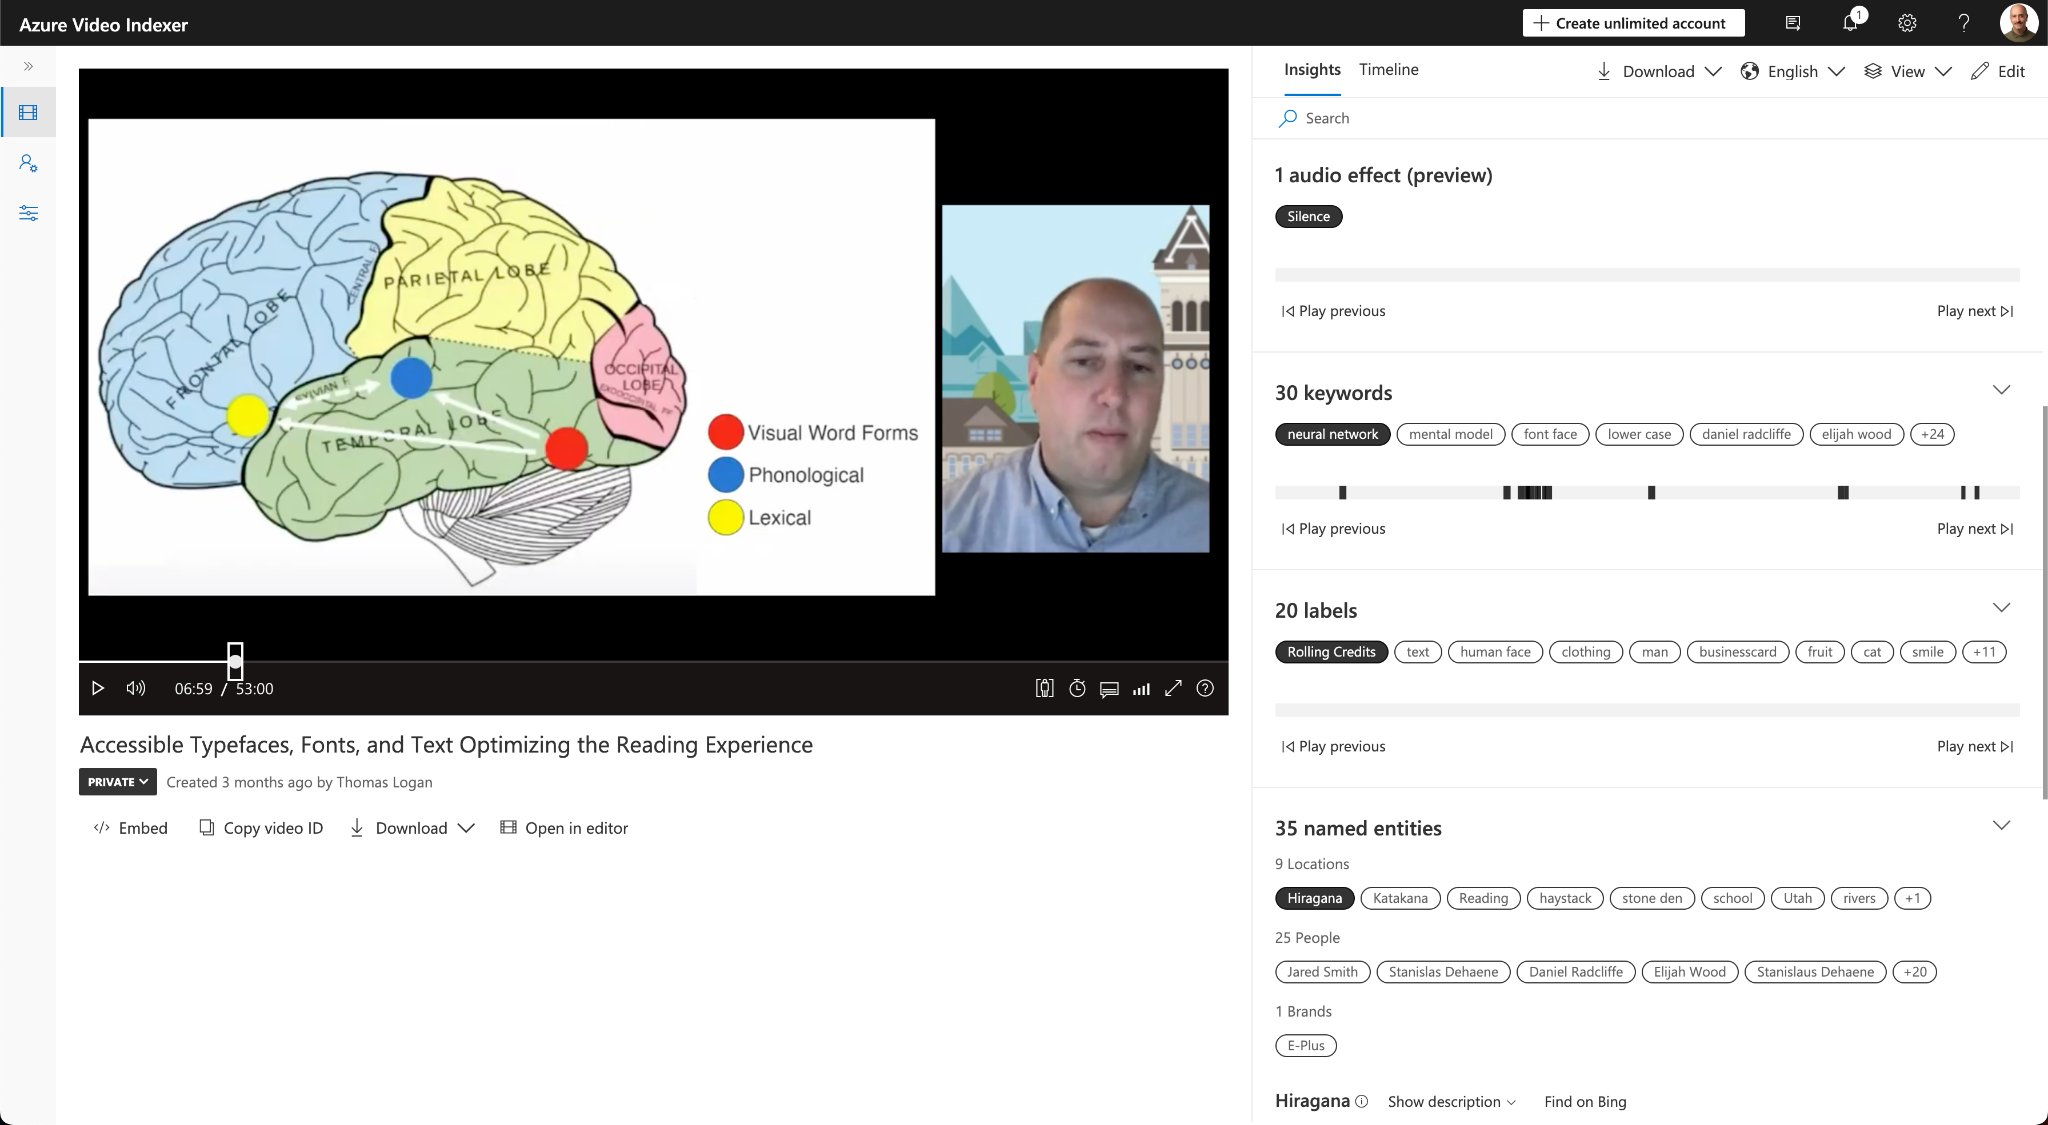
This tool finds keywords, labels, and named entities inside the video. It provides extra logic that goes beyond captions. It’s also trying to do some semantic understanding of the video and provide links. For example, if someone selects a named entity of Elijah Wood or Daniel Radcliffe, the video will jump to where the proper noun was mentioned.
It also offers translations of captions that you can download and work with inside the tool. Another thing that’s interesting in the Azure Video Indexer is the download of the caption VTT file includes a confidence value. This shows the percentage estimate for how accurate or not the caption is.

If something has a 40% confidence versus a 29% confidence, the lower the confidence, the more likely it’s incorrect. This API displays this statistic on each line of captions. We didn’t do explorations here, but it’s a good area to explore. People who want to improve AI systems can use these confidence values. People can focus on the lower confidence values and check the accuracy.
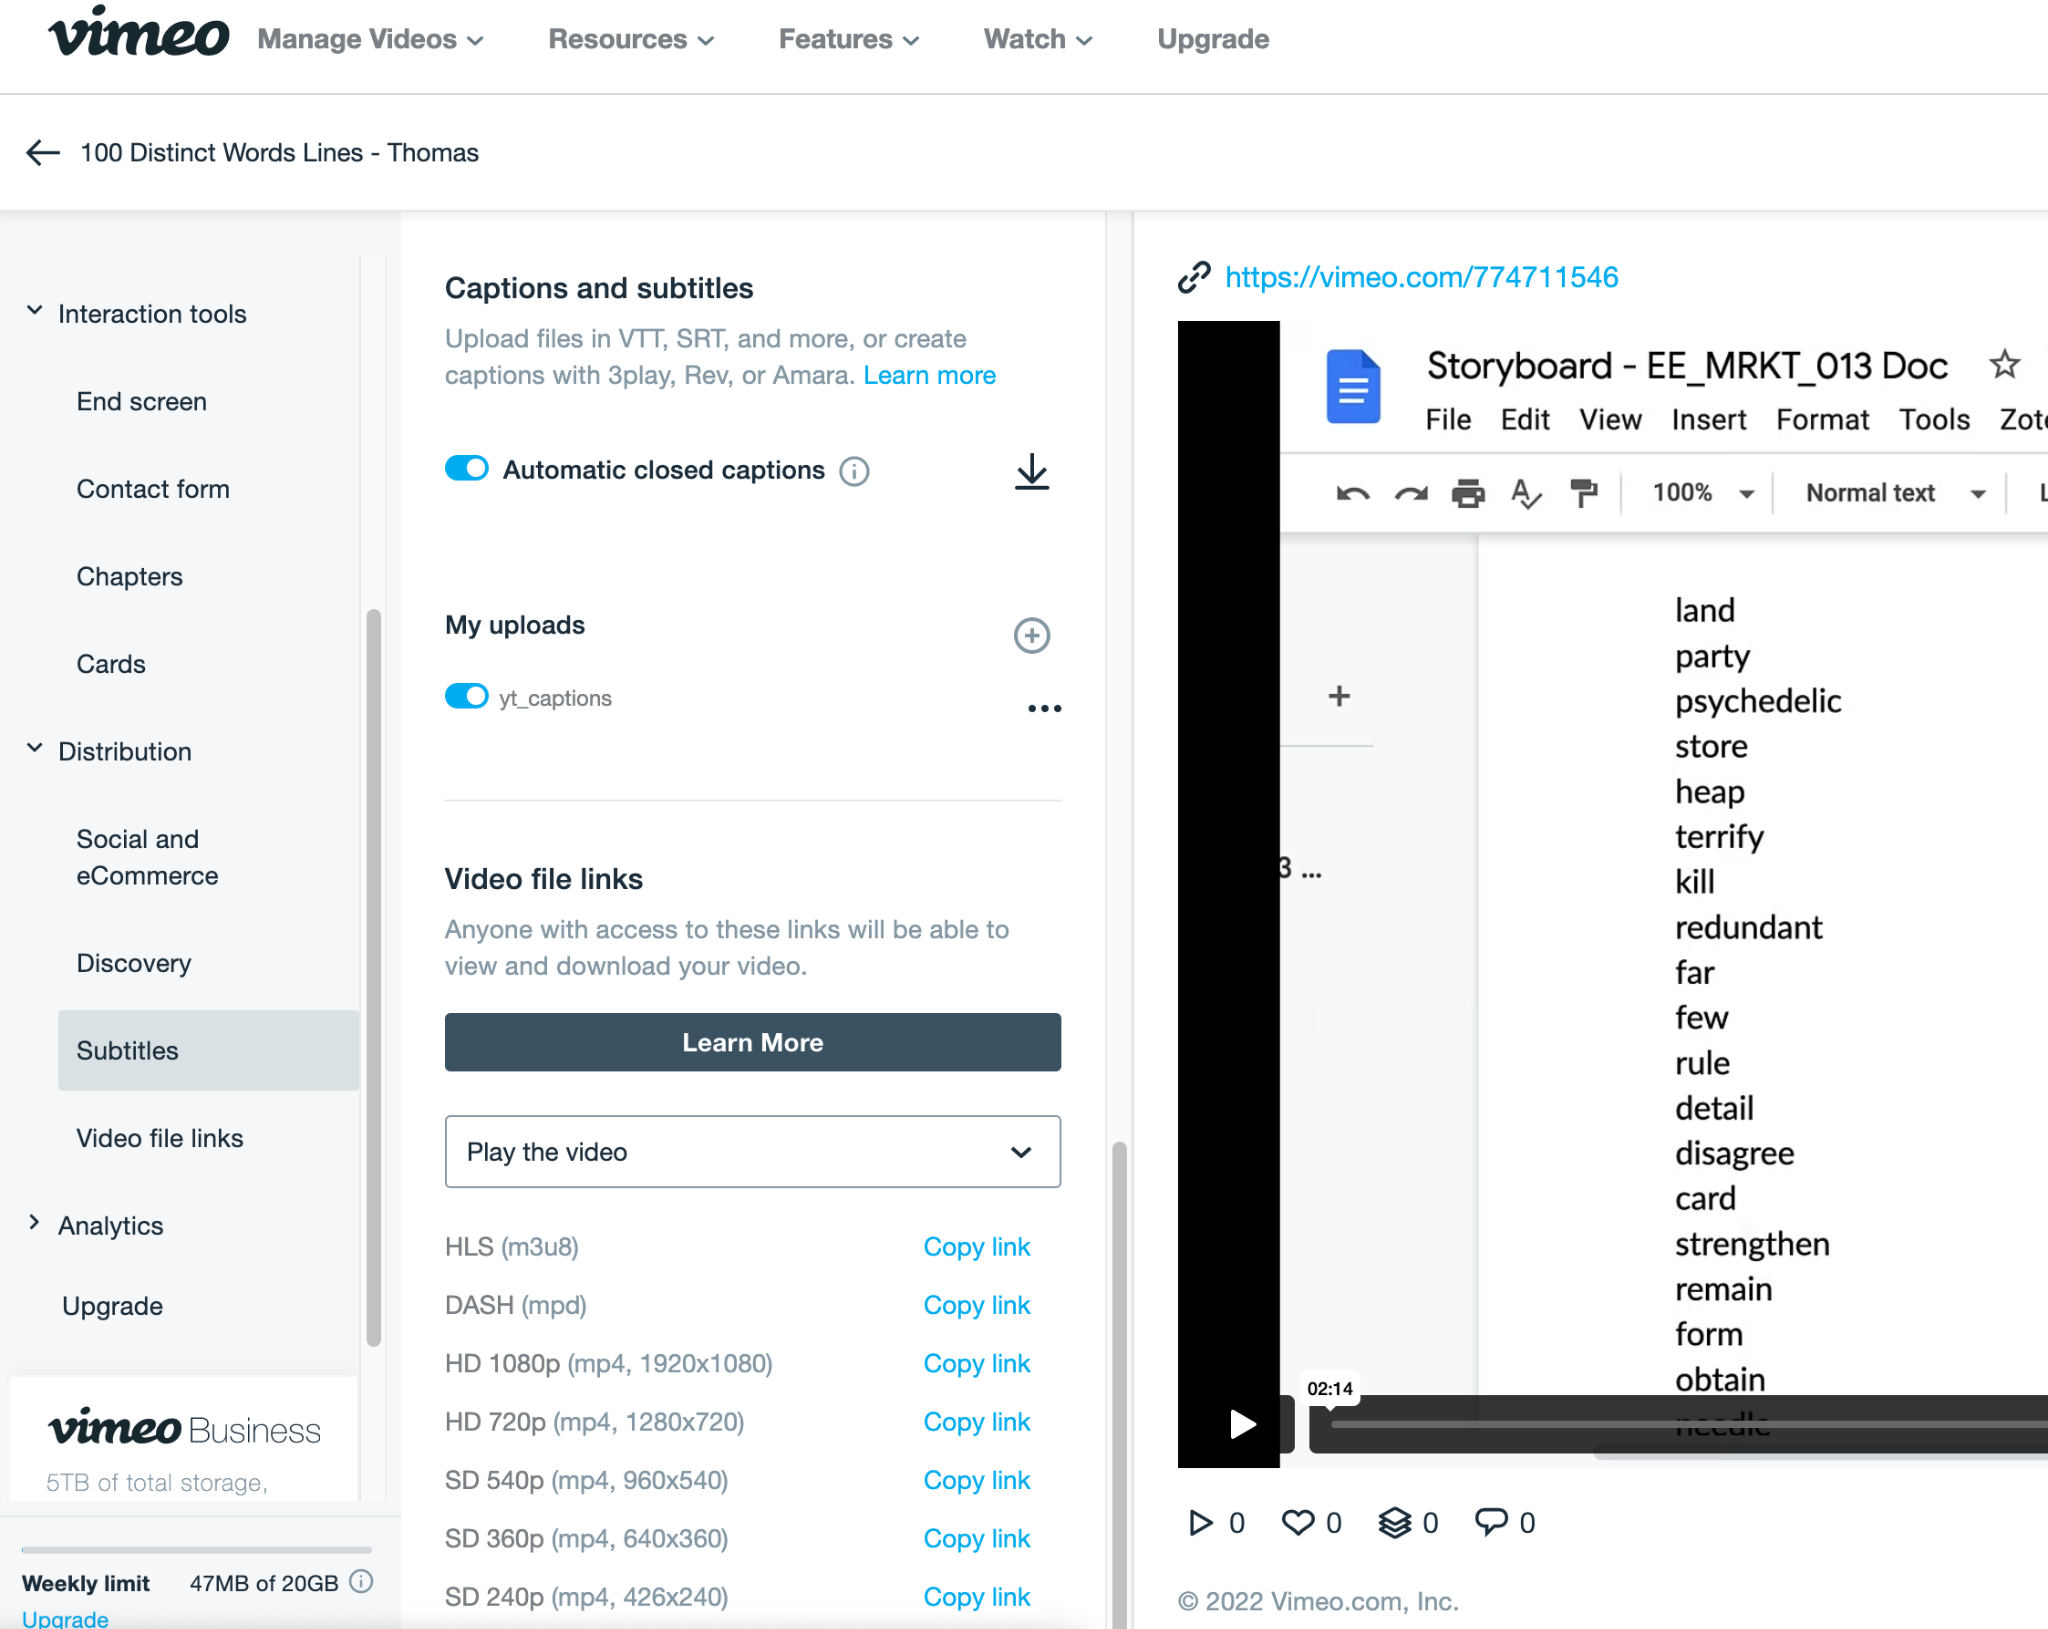
The next platform is Vimeo, which uses Google engines for AI captions. Paid Vimeo account holders can download the AI captions.
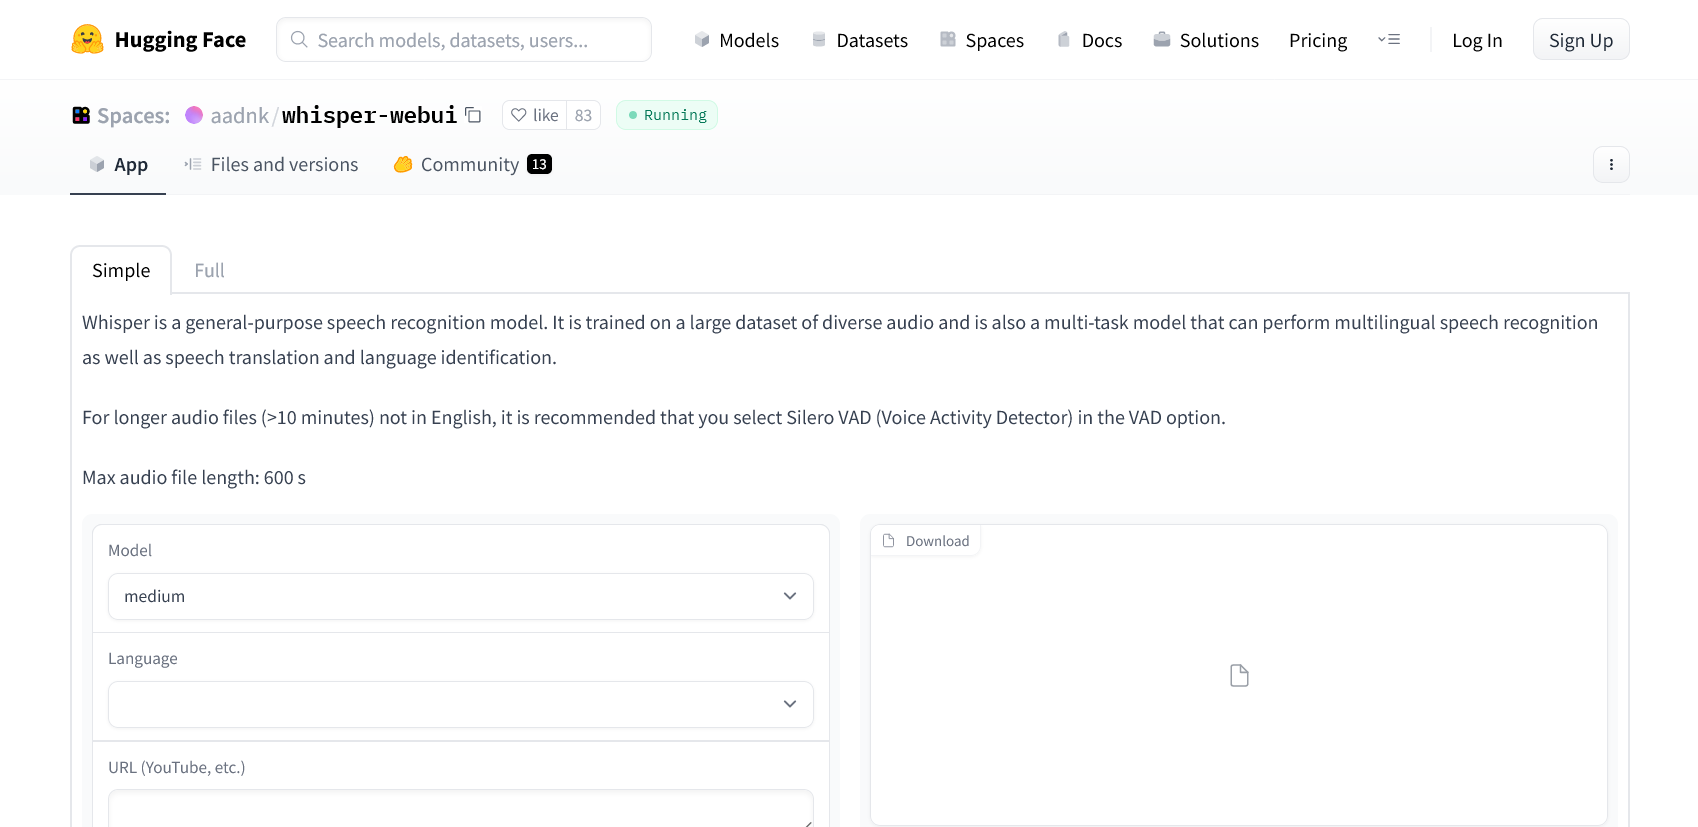
Last but not least is Whisper. It uses OpenAI, a system that everyone is talking about because it’s behind ChatGPT and DALL-E. Whisper is OpenAI’s automated captioning service. What’s interesting about this technology is it has different models for translation.
They have this idea that they’d ask how many voices the video will need to compare against. The more computation time you spend, the more accurate the translation will be. This lets you choose how accurate you want the AI captions based on what you’re willing to pay. If select a large model, it’ll be more accurate than the small model.
Test Cases for Captioning
Our Equal Entry team is passionate about finding ways to make captions better. We’re fortunate that the team consists of people from all over the world including the U.S., Japan, Brazil, the Philippines, and India. Automatic captions are notorious for being more accurate with English with a plain American accent. Someone whose first language is English but has a British or Australian accent is less likely to be as accurate as someone with an American English accent.
Everyone on the team speaks English. Some as a first or only language while it’s a second language for others. Then, there’s me. I was born in the U.S. and my first language is English. But I have an accent that comes with being born profoundly deaf. All the captioning AIs agree on one thing, they don’t do well with my accent.
Thomas and I want to thank Kevin Vaghasiya for his work in setting up the research and automating the processes for our test cases. Our team made a Google Sheet consisting of the different test cases. We compared them using AI from Vimeo, Azure, YouTube, and Whisper. The spreadsheet shows some statistics to measure how well the service is captioned or not.
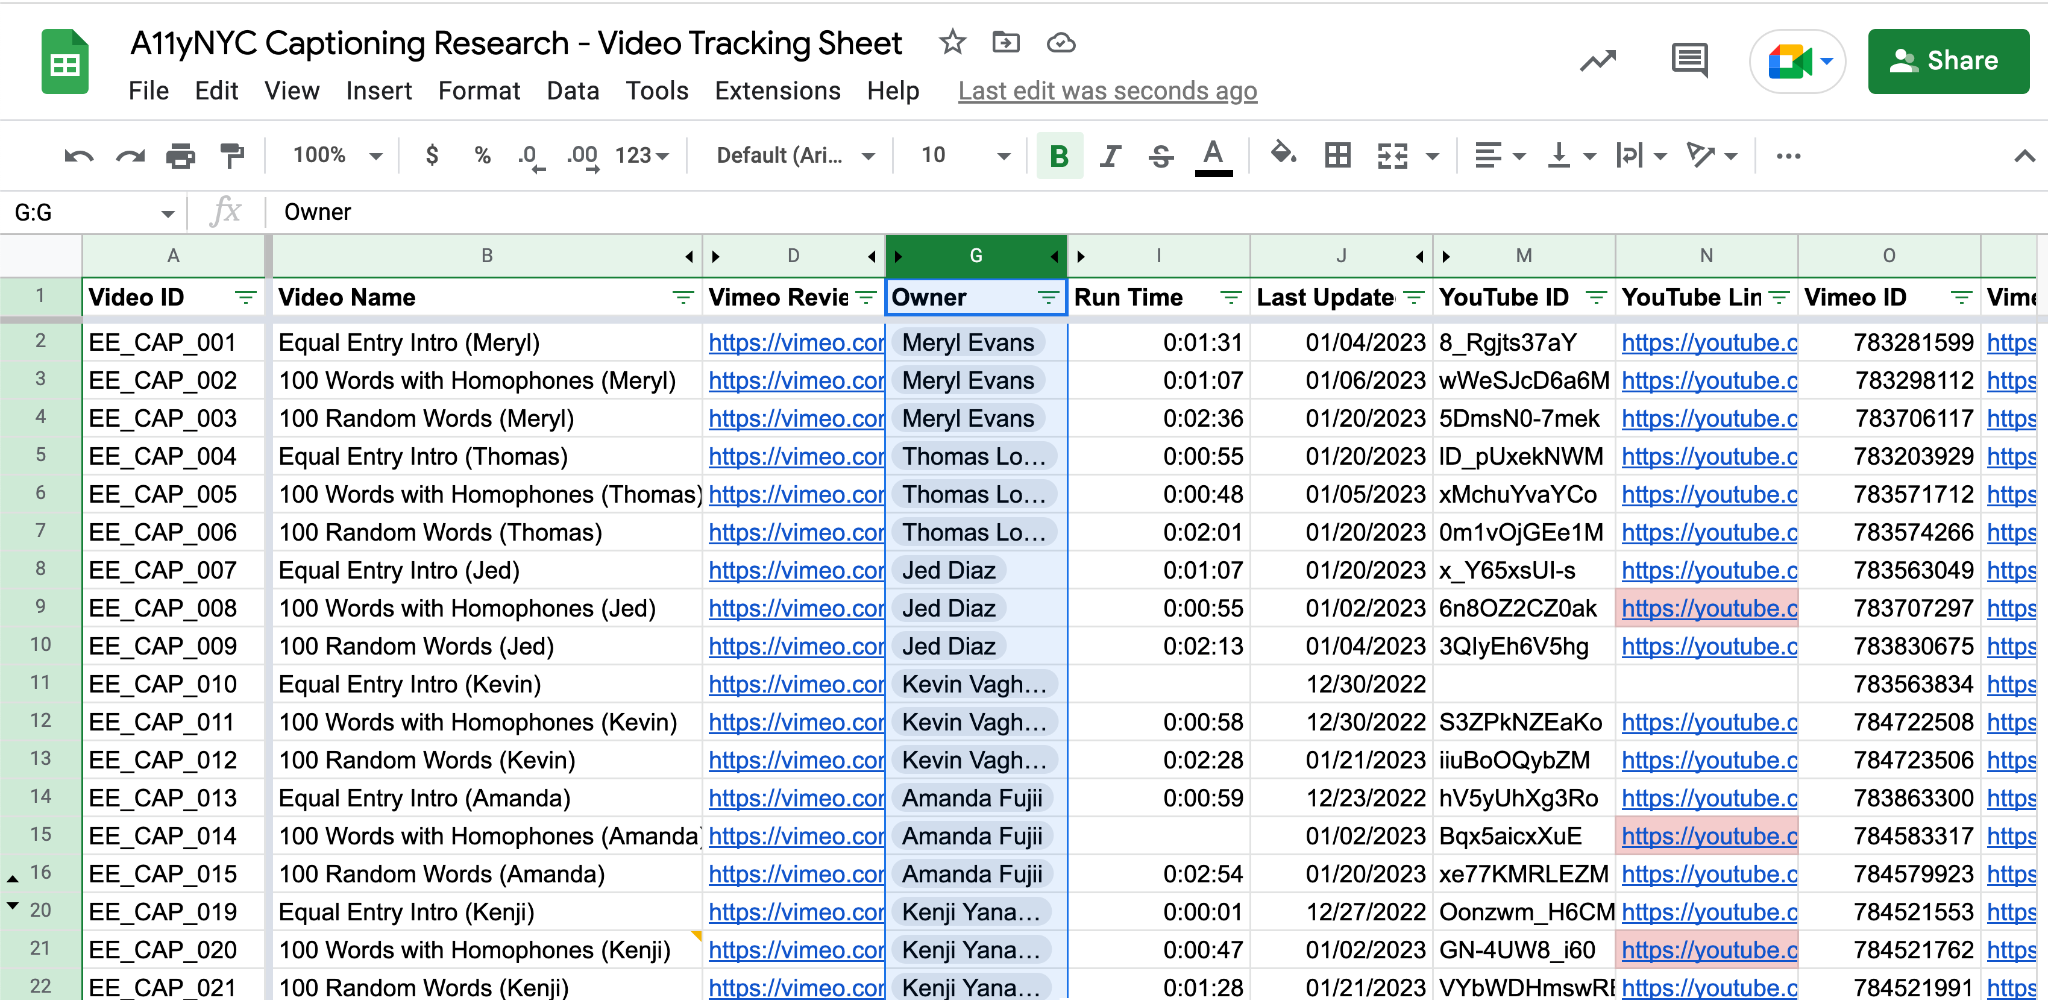
We created three test cases with six people doing each one for a total of 18 videos. Kevin created a Chrome plugin to automate the uploading process. Our thinking is that professionals want to scale the automatic captioning process as they have hours and hours of videos. The idea is that people will use APIs and automation to scale the process of adding accurate automatic captions to videos. That’s the dream.
The team wants to find a way to compare the captions or look for problems inside the files. The spreadsheet allows us to pick any file and do a comparison of the captions between the Gold and the AI. Gold captions are based on the script we wrote. We pull up the Gold captions and one of the AI services like Azure. It highlights the similarities and differences. We created three scripts, each containing 100 words. We wanted to have one variable that was the same for all of them.
Test Case No. 1: Equal Entry Intro
Our first test case was doing an introduction to our company, Equal Entry. This test focuses on proper nouns and acronyms. AI systems tend not to do these well because they don’t know what is important to someone. “Equal Entry” is important to our team but not to the general public. Words like “macOS” and “iOS” have specific ways to be identified.
AI systems won’t be familiar with niche terms and phrases like VPAT, which is Voluntary Product Accessibility Template. That’s a known term in accessibility, but not so much for outsiders. This test case also includes W3C, WCAG, A11yNYC, and A11yTokyo along with less commonly used words.
I shared a few screenshots from my intro video. Here are the accurate lines and what YouTube’s automatic captions showed.
Correct line
macOS, Windows, iOS, and Android.
We produce accessibility conformance
Captions
Mac OS Windows IOS and Android
we produce adaptability confirming
YouTube’s captions rarely contain punctuation and capitalization except for the occasional proper nouns as these captions show. However, it did not format Apple’s operating systems correctly.
Correct line
We improve access to technology
for people with disabilities
Captions
we improved actor to technology the
people with disabilities through
Just changing one word from present to past tense and using the incorrect word makes it hard to understand what the captions say.
Correct line
W3C work tag the death criteria?
W3C WCAG success criteria …
Captions
that will include our findings related to
the w3c work tag the death criteria
AI did not properly capitalize W3C and turned “wuh-cag” into “work tag” and “success criteria” into “death criteria.” Although the latter seems accurate as WCAG is notorious for being hard to understand.
How did the AI do with “A11y” as in “A11yNYC,” A11yVR,” and “A11yTokyo”? It did not get one right in any of the test cases. We tried ally (rhymes with apply), alley (as in bowling alley), and A-eleven-Y. The only way it’d get it right is if someone said the full name as in “Accessibility New York City.”
Test Case No. 2: 100 Random Words
The next test case was 100 random words. And we did this test case to determine if AI looks at the context of how the words are used. The purpose of this is to confuse the AI in the sense that there is no context. The following are the 100 random words we used and worked to avoid those with sound-alike words.
land, party, psychedelic, store, orange, terrify, love, redundant, far, few, rule, detail, disagree, card, strengthen, remain, form, obtain, needle, serve, outrageous, trousers, purple, fine, massive, sticker, tramp, mass, test, reflect, last, desk, snobbish, believe, raspy, top, impress, candle, miniature, insect, doctor, unadvised, cry, ship, uptight, puppy, weekend, plot, windy, blink, club, relax, wing, mask.
Here are some of the words and what AI thought the speaker said.
| Correct word | Automatic captions |
|---|---|
| abhorrent | a point |
| abhorrent | adherent |
| abhorrent | uphorrent |
| chivalrous | shiver |
| chivalrous | she wellness |
| lowly | nothing |
| lowly | slowly |
| lowly | lonely |
| lowly | lovely |
| stir | star |
| stir | steer |
| stir | still |
The following comes from my own 100 random words test. The script is the correct word. Then, the other three columns are the three different AIs.
| Script | YouTube | Vimeo | Azure |
|---|---|---|---|
| psychedelic | psychedelic | back a delic | that Cadillac |
| disagree | disagree | there’s a green | with a green |
| snobbish | cannabis | nabis | |
| uppity | I | A body | apparently |
How did Vimeo get “cannabis” from “snobbish” and Azure somehow shortened “cannabis” to “nabis”? I joked that YouTube was exposed to cannabis and forgot to caption “snobbish.”
From what the results show, it looks like there’s a little context that goes into the AI. But it’s not necessarily looking at the full sentence structure. Our hypothesis is that it may be looking at the previous and next words. As the 100 random words test shows, the AI performed worse because it had no hints to help it along.
Test Case No. 3: Homophones
Homophones are when two words have the same pronunciation, but different meanings or spelling. Here’s an example: their, there, and they’re. The point of testing homophones is to see if the AI considers context when determining what word to use.
The following video shows four versions of the same video with me. The upper left contains the script, which contains accurate captions. Below that is Whisper. The upper-right uses Azure’s AI, and below that is YouTube’s automatic captions.
Be aware that some people told me these videos are too much. You might consider moving the video player slider to jump around scenes. Then you can compare the captions without playing the video.
As for the results, the most accurate captions came from Whisper followed by Azure. YouTube doesn’t deserve to place due to its roll-up (moving or scrolling) captions, noticeable delay, and lack of capitalization and punctuation.
Recommendations
Companies taking a progress-over-perfection approach to captions would start by adding captions if they’re not already. There are companies that aren’t using automatic captions on social media platforms. Hence, adding captions is the first step. The next step is to edit the automatic captions. Make reviewing and editing automatic captions part of your video workflow.
One thing AI doesn’t do well is line length and line division. Line length is the length of each caption line. Line division is where the captions end on each line. Some refer to this as line breaks.
This video shows two side-by-side videos. The captions on both sides are accurate. The difference is that the left one follows line length and line division best practices. The right side shows how AI does line length and line division.
In short, AI doesn’t pay attention to line length and division. Following line length and division best practices make a big difference to the viewing experience. It reduces cognitive overload. Captioning Key has an excellent guide on line division.
In our work, we use a lot of the same words, acronyms, and phrases. These include W3C WCAG, a11y, NVDA, JAWS, operating systems, VPAT, and accessibility conformance reports to name a few. There are transcription services like Descript and Otter.ai that allow you to add custom vocabulary. The capability exists.
Currently, none of the AIs in the test cases allow users to add custom words. If these services want to make progress in improving automatic captioning, then they’ll let users create accounts to add custom vocabulary.
Any time you don’t see captions or edited automatic captions, contact the company and ask for them. Some companies have come through.
YouTube captions need the most help. So, contact the Google Accessibility Team about YouTube captions. Google owns YouTube. Ask them to please use punctuation and capitalization. One other thing to mention is to use pop-in captions instead of roll-up in a recorded video. The other AIs don’t do roll-up, so it’s doable.
Learn from Netflix
It’s possible to turn things around with accessibility and captions. In the past, Netflix got sued for lack of captioning. Now, they’re a leader. Netflix has high standards for subtitles and closed captions for all of its content.
“This is because at Netflix, Subtitles and Closed Captions are Primary Assets,” Netflix writes. “Subtitles and closed captions have historically been deemed a secondary asset. Even our own technical specification lists subtitles and closed captions (timed text) among several types of secondary assets that NETFLIX requires. The reality is that for millions of our members around the world, timed text files are primary assets.”
Netflix has a quality control process, even for subtitles in a different language. The little things in the translation are critical. They give an example of subtitles showing “Let me refresh your mind” instead of “Let me refresh your memory.” Little things like using the wrong word can disrupt a person’s viewing experience.
They’ll have someone who doesn’t know the language of the program watch a few minutes of content. If they come across anything that doesn’t read well, Netflix rejects the file. They expect companies to check things like this before sending the asset to Netflix. The company also pays attention to readability and speed.
The takeaway is to randomly select two to three minutes to watch to check the quality of the captions or subtitles. If it doesn’t pass, then send it back to the partner. After the partner resubmits the file, then check a different two to three minutes. It’s a more practical way of spot-checking the quality.
Do you care? For captions to improve, everyone needs to make their voice heard and send feedback. Advocate and push for changes.
Watch the Presentation
- Why quality captions matter
- AI captioning services used in test cases
- Test cases and results
- Recommendations
- Q&A with Thomas Logan and Meryl Evans
Transcript: Automatic Captions: Our Experiments and Best Practices - Thomas Logan & Meryl Evans
THOMAS: Meryl Evans and I are gonna be speaking tonight about automatic captions. Our experiments and best practices. I have on the screen a QR code. You don't need to scan this right now.
But just know that all of the items that we're referencing in today's presentation are also going to be linked from this QR code, and it will also be shared out on social media, to access it. I'm gonna hand it now to Meryl!
MERYL: Thank you, Thomas. So... I'm always excited to come to New York City! Because of the people.
I get to see all of you. But I was extra excited, because it was going to be my first Broadway show in a long time. And with captions! I have never been to a live show with captions.
And I could not wait to see MJ, the Musical, about Michael Jackson. The image shows a Playbill with the cover of Michael Jackson. And next to the Playbill is a smartphone that says "intermission". Like most Broadway shows, the show uses GalaPro.
So how did it turn out? Well... Instead of "Thriller" experience... GalaPro told me to...
"Beat It!"
THOMAS: Boooo! (laughter)
MERYL: Within a few minutes after the show started, the captions got stuck on a line for an hour. A while. A long time. And I wasted a lot of time troubleshooting and getting frustrated.
Instead of fully enjoying the show. So what can be done? I submitted feedback from the app. And it would help if GalaPro had instructions saying what to do if the captions don't work right.
I don't know if that's possible. But it would have helped! And then I wasn't going to get up and report it. and disturb my fellow theater attendees.
Make everybody get up so I could get by... I mean... To interrupt everybody. Over to you.
THOMAS: Yeah. And I just want to say... The experience was not pleasant for myself either. Sitting next to Meryl and thinking we were gonna have this great experience.
I just think... From my standpoint, I even question myself... Should we have gotten up and walked out? Because this just happened at the Sundance Festival.
Something with Marlee Matlin attending a juror award. And they did walk out. And it is very disappointing to have this technology be... You know, offered as available, and not work.
So as Meryl said, I think a best practice should be: What's the backup plan? And/or what's the way to report something's not working? Because it was definitely not... It was a horrible experience for Meryl.
It was a horrible experience for me being like... Wow. This is not working. Because the show is great.
If anyone's seen MJ, it's a great show. But it would be much better if it was accessible. So... Current events!
Why do quality captions matter? Well, that's one reason. Back to you, Meryl!
MERYL: So... First of all, please note that when I talk about captioning best practices, I'm talking about best practices for everyone. Not my personal preference. So often, people get so confused.
My own personal preferences do not play into when I'm talking about captioning publicly. Unless I specifically say: "I do not like this." Then you know that's my personal preference. Anyway...
The number one rule for high quality accessible captioning is readability. After all, if nobody can read your captions... Then none of the other rules matter! Right?
So... People put so much effort into adding captions. It's such a shame when they make bad caption choices that you can't use them. This is a screenshot of me on a video, side-by-side, same video.
One side says "none of the other rules matter". In regular captions. Black with white. The other one shows yellow captions, with no background, which makes it -- as you can see they're kind of disappearing into my white skin.
So readability includes background colors, fonts, and size. The best captions are boring. They let the video be the star! And they're out of the way until you need them.
Thomas?
THOMAS: Great. So we're gonna start... We told you we would give you some best practices, solutions. Best practice number one...
Hire an amazing human captioner! Today we have Mirabai Knight, who is captioning here live in the room, and we've worked with Mirabai from the beginning of doing this Meetup. So before we even really delve into the details of what we want to present here, that's already the starting point. Work with a human captioner.
Because a lot of the things that we're going to be speaking about in today's presentation really illustrate why you can't rely on an AI solution. And we never have at our Meetup. And we've really benefited from working with Mirabai Knight. And we will post links for you to contact her.
She is available for conferences and some other new experiences. And we've always been really fortunate to get to work with her for our events. And she had a great presentation at Accessibility New York City in March of 2019, Why Human Captioning?, so we will also link out to that. But that's a very detailed explanation of a lot of the reasons to consider and not rely on automated captions.
Now we're gonna dive into our work at Equal Entry, on looking at AI captioning services. And what we tried to do was go through four very popular services. You may not be familiar with all of these, so we wanted to just first set you up with: These are four of the biggest services that exist. The one that I'm sure everyone's familiar with is YouTube.
And you are able to receive automated captions for most videos that you upload to YouTube. When you upload a video to YouTube, you set what language the video is being spoken in. You pick one language, and that will typically create AI-generated captions for the video. And after the fact, you can download those subtitles, and work with them, as a set of formats.
And on the screen, I'm showing that you can download some file formats. VTT, SRT, and SBV. And we'll talk about those a little bit later. But...
I would say this is the most common use case, is people are familiar with -- you can upload videos to YouTube and get automated captions. Another cool piece of software that I believe probably many people here wouldn't be familiar with is from Microsoft. It's called Video Manager Azure AI. When you place your video into this system, it is a paid system.
So there is a trial, where you can get some of this functionality for a certain amount of video content for free. But eventually, this model is different from YouTube, where you're paying for each video you upload. So on the screen, I'm showing a video from a previous Accessibility New York City presentation. Accessible Typefaces, Fonts, and Text, Optimizing the Reading Experience, from Jared Smith.
That was a great presentation. One of the things that you'll see with this tool is that it will actually find keywords inside of the video. It will find labels. It will find named entities.
So it's doing some extra logic. It's not only providing you the captions from an AI system. It's also trying to do some semantic understanding of the video, and it's giving you links. So, for example, if I click on a named entity of...
Elijah Wood or Daniel Radcliffe, it's gonna jump into the video where that proper noun was mentioned. And it's actually a cool system too, for getting translations of captions. You can download translated captions and work with them inside of this tool. Another thing that's pretty interesting in the Video Manager Azure AI is when you download the VTT file, you get a confidence value that is a percentage estimate for how accurate the caption is.
So that's pretty cool for developers in the room. You can use something interesting with this to say. If something has a 40% confidence versus a 29% confidence, the lower the confidence, the more likely it's incorrect. And so that's something that, per line of captions, you can get that from this API.
And we didn't do explorations here. But I think it's a really rich area to explore, for people that want to improve AI systems. Use these confidence values. The higher it is, maybe tell people: Don't focus on those areas.
Look at the lower confidence values, and make sure that those are accurate. So it's an opportunity. Vimeo... We're not clear if anyone in the room is from Vimeo.
Does anyone here work for Vimeo? Okay. No. I'm not sure what Vimeo uses for their AI generation.
But it's interesting. We have a paid account with them. It's very fast when you upload a video to Vimeo, to get the AI generated captions. I hypothesize they're using maybe a service like Rev.com.
But I don't know. I don't think they expose that, who they're using. But you can... If you have a paid Vimeo account, receive the AI captions.
So we have done that as part of our research for today's presentation. And the last one is... This is probably a strange-looking screenshot. Hugging Face is a GitHub link that we have.
But this is using OpenAI. So people that have heard in the news... ChatGPT, DALL-E, that we showed the image recognition -- this is the AI system that everyone's talking about. This -- Whisper is OpenAI's system for transcription.
And one interesting thing to note for this technology is: They have different models for translation. So they have this idea... Maybe based off of price and computation time, how many voices do we need to compare against? And so the more computation time you spend, the more accurate the translation is.
So it's interesting, as a comparison, to other AI systems. That you can choose, based off of what you're willing to pay, how accurate do you want it? And if you choose a large model, it'll be more accurate than the small model, typically. All right.
Now let's go to our test cases. So this was Equal Entry's process. And we're passionate about making captions better. I have to say working with Meryl has been a huge inspiration to me to understand that captions aren't just...
You have captions. They need to be good. And also just want to celebrate that the people I work with at Equal Entry are very global. And all over the world.
So one of the ideas for our test cases was we wanted to highlight that we have English speakers that don't come from an American background. So maybe English... Not as a first language is an interesting use case, similar to a person such as Meryl Evans, who was born hearing-free.
MERYL: In medical terms, profoundly deaf, but hearing-free is more interesting.
THOMAS: You know, this is something that's somewhat known, right? That a lot of these AI systems are really targeted to a default accent or a default voice. So we wanted to highlight in our work that we have people such as Kevin from India, Amanda, who is from Brazil/Japan, Jed from the Philippines, and Kenji, Japan. All of them speak English, but with accents.
And we wanted to put them into our thought process, in the same way, too, that a person with a deaf accent, a person with an accent from a country that's maybe not trained on these systems, may or may not have a good experience with the translation. Skip this. I want to say thank you to Kevin -- on the screen, this is just to show you -- we're not gonna spend a lot of time, because we only have a tight limit here, but I put this screen up to show...
We did do a lot of technical work. And I really thank Kevin for his work on setting up our research. We basically made a Google Sheet that has all of these different test cases that we'll be talking about tonight. And we compared them inside of Vimeo, Azure, YouTube, Whisper.
And we came up with some statistics and ways to measure how well they're done. So we did three test cases and we did six people. And inside of each experience, I can just pull up one of the examples. We have a way to...
Sorry. I have to pull that up on another screen. Live demo! Here we go.
I'm gonna pull up a plugin that we made, where we actually have a way to upload our videos and automate this. And I think this is important as an understanding for professional use cases for captioning. People have tons of multimedia content. So we're sort of emulating this idea that a lot of people are gonna be using APIs and automation to get automated captions.
And we're trying to add in: How can you compare them or look for problems inside of them? So we can pick any video that we created. This is me talking about Equal Entry. I can say "compare captions".
And what we've done is create a way for us to pull down the captions from... We called the gold caption the accurate caption. So in our work, we have actually written out what are the right captions. And then we can select a different tool, such as Azure, and see how many different words did they add.
What's the similarity between them. So we'll be talking more about this, I think, in later blog posts. But I just wanted to show you... We're building this to actually also use it for our Meetup here.
Accessibility New York. We want to start improving from what we put out. Like, can we find areas to fix, and can we find problem areas? And so this is something that we typically...
If you have what the captions should be, you can do this analysis. And we also have this feature, to see where the mistakes are. And we have a visualization too, using red and green, to sort of put the comparison of what was done in the official caption with the compared caption. And I'm gonna keep moving.
Because we don't have tons of time. So our first test case was doing an introduction to our company, Equal Entry. And what we focused on with this test case was proper nouns and acronyms. These are things that don't do well with AI systems, because AI systems don't know, often, words that are particular to a domain or to your life.
So in my life, the word "Equal Entry" means a lot. It doesn't mean a lot, maybe, to the general public. And even words like "MacOS" and iOS, these have specific ways to get spelled and written out. But they aren't words that would necessarily be translated by an AI system.
VPAT, Voluntary Product Accessibility Template, for those of us that work in accessibility, that's a word we know. But that's, again, not a word that's optimized for these systems. We did W3C. We did WCAG.
And we did A11yNYC and A11yTokyo. Also definitely not commonly used words. I'm gonna switch to Meryl now, to talk about some of the experiences with doing the test.
MERYL: So I was born here in America. I am a native English speaker. Yet one thing that automatic captions all agree on: They agree they don't like my accent. So...
And it's not a British accent, it's not a Texas accent. But I say "y'all" a lot to make up for it. So the caption in the screenshot shows: MacOS, Windows, iOS, and Android. We produce accessibility conformance.
That's the correct way. But the captions below say: Mac -- capitalized -- OS. Windows IOS completely capitalized, and Android. We produce adaptability conforming.
Makes no sense. There are no commas. "we" is the start of a sentence. Therefore, it should be capitalized.
And it's hard to figure out, without the punctuation. Next example. The captions in the screenshot have just one wrong word, and one word changed from "improve" to "improved", and it's missing a short word. "for".
What I actually said was: We improve access to technology for people with disabilities. The captions say: We improved actor to technology the people with disabilities through. Pretty messy, huh? I mean, not a whole lot of changes, but it managed to not make much sense.
And then the last example, I promise. I can't help but laugh at this one. So the captions say that we'll include our finding related to the W3C work tag the death criteria. So "W3C work tag the death criteria" should be...
"W3C WCAG success criteria!" Although the death criteria sounds more accurate because... As many of us know, the WCAG is very hard to understand. (laughter) So now it's your turn.
Ignore what Thomas said earlier, on how to pronounce -- how do you pronounce a11y? I'm just spelling it out. I'm not saying that's how you pronounce it. So we have four choices.
One is "ay-eleven-y". Two is a-one-one-y. Three is ally, as in alliance. And four is alley, like bowling alley.
So raise your hand if you do the first one, which is a-eleven-y. I would say about half the room-ish raised their hands. And then how about number two? A-one-one-y?
I would say about a third, I think. And then number three? Ally? One, two, three...
Four. About four. And then finally... Alley?
Number four? One, two. (laughter) Three? Okay.
So... It's whatever you want. But I love a-eleven-y. For those who don't know, the reason it's A-eleven-Y is because there are 11 characters between the letter A and Y in "accessibility".
Pssshhhh! (laughter) It's called a numeronym. Did I say that right?
THOMAS: Numeronym.
MERYL: Okay. All right.
THOMAS: Yes. So... You know, that's just one example of... I think a-eleven-y, alley, ally, ...
That's a really great example of... Even with us in the room, how could an AI hear all of the different ways we say it and know it? That's already something that needs to be addressed and considered and thought about. And currently isn't.
And you can see in our test cases... It never got it right! In how any of the six people that tested it pronounced it. Unless you said "Accessibility New York City", the full word...
That worked. But if you do anything else, it doesn't work. The next test case was just 100 random words. And we did this test case to say: Does AI look at the context of how the words are being used?
And we wanted to do this one, just to try to confuse the AI in the sense that there is no context. It's just 100 random words. So on the screen I have some of the 100 random words. And it's not meant to read all of these words.
But... There's words like "psychedelic", "maths", "miniature". It's kind of weird, when you pick 100 random words, by the way. We had to edit out some of the ones that came up.
MERYL: (inaudible)
THOMAS: Yes, and we had to consider... We wanted these 100 random words to have unique pronunciations, because we wanted it to be something that should be deterministic for the AI And here's an example of some of our results from our team. Some of the ones that popped out, that were interesting across the team. Abhorrent came up "appoint".
Adherent. And aphorent. Not familiar with that word. Chivalrous became shiver.
She wellness. And shivers. So... Depending on a person's accent -- these were different people using the same AI engine.
Phony, for, and for me. So two times it said for me instead of phony. And we had snobbish. I'll just jump to one last one.
Cannabis. Snobbished. And knowledge. So it was interesting just to do this.
There's no context. So it actually does... I think from what we've seen, there's a little bit of context that goes into the AI. But it's actually not looking at the full sentence structure across any of them.
I think it's only doing next and previous words. That's still our hypothesis. And we did see that with the hundred random words, it performed worse, because there is nothing to pull from to make them better.
MERYL: So... deaf accent is back. We have a table of words. The first one comes from the script, which is the correct word.
Then YouTube, then Vimeo, then Azure. So, looking at my results, they got less than half right. Sorry, three got less than half correct. That was pretty sad.
So I'm sharing some that are so far off the mark that they'll make you laugh. So psychedelic -- Vimeo thought I said "back a delic". Where Azure thought I said "that Cadillac". I'm not talking about cars here, y'all!
Then disagree -- YouTube got that one right. But then Vimeo and Azure, for some reason, think I said "green". And I'm like... Where did the "n" come from here?
I didn't say disagreen. I said disagree! And Thomas already gave it away. Snobbish.
So YouTube just went silent. But I think it got high. So it forgot to caption the line. And then Vimeo did "cannabis"!
So it probably affected YouTube that way. And then Azure was so lazy, it only did half of "cannabis". Then finally, we have uppity. YouTube was probably so tired, it did one syllable: "I" Then Vimeo, they must have been smoking a lot, because they said "a body".
And finally, Azure is the real winner with "apparently". How "uppity" became "apparently", I have no idea. I hope it's obvious from me saying it.
THOMAS: All right. And our last test case was just using homophones. And we had fun with this, to see if they are using the context of the word. A homophone is something that sounds the same, but is spelled differently, and has a different meaning.
So "there", THERE, "their", THEIR, and "they're", THEY'RE. We created a set of 100 words that used these cases. I was very happy with this image we made for this. It probably wasn't explained well, as advertising this Meetup.
But we worked with Lila Ash to create this. It's a mash-up of the idea of Bart Simpson writing on the chalkboard, and a New Yorker style of illustration. And what we did was show that we put in... We're supposed to say "I bought ten tin cans".
So, on the recognition of that word, we had different spellings. We had "I bought ten pin cans". And sometimes ten is spelled as "10", sometimes ten is spelled T-E-N. And that was another just interesting thing, is the plural and non-plural came up in our results.
So the -- in different people's accents, the plural of a word came up as a big difference, I think, for people that were native English speakers and non-native English speakers. Just from what we observed in our study so far. And now...
MERYL: All right. So, here I have a video of four versions of me. I'm sorry there's so much of me! (laughter) So it's the same video.
We have in the upper left corner -- it's the script. Which is the correct version. Below that is Whisper. And then upper right is Azure.
And below that is YouTube. So, I have heard from some friends who have ADHD and other disabilities that watching a video like this is overwhelming. If this bothers you, you might want to look away for a little bit. Think about something else.
And I'm gonna play a little bit of it, and then I'll talk through it. This video is online. It will be in the resources, if you want to watch it yourself in slow-mo, so you can compare. But you'll get the idea from watching.
And I'll give the results later. I don't want to spoil anything.
MERYL: All right. So you saw the winner. The best one was Whisper. Followed by Azure.
And I don't think YouTube deserves anything, period. YouTube's roll-up captions are bad enough as-is, and they were way behind, as you probably saw. And Whisper had the most accurate words. Whisper and Azure -- I really appreciated they were not roll-up, which is moving captions.
And a recording should not be animated captions. It should be pop-in, traditional. The only time that roll-up captions is justifiable is in live programming. Because captioning live programming is so, so hard to do that I tend not to watch things live.
Because it's just hard to take it in. There's a lot of cognitive overload. Okay. So, I am going to talk briefly about caption file types.
There are many, many, many caption file types. But most of us will use SRT, which is SubRip Subtitle. You can see why we call it SRT. And WebVTT, which is web video text tracks.
And so the many more that are out there are mostly professional entertainment, like TV, movies, they have a lot more options. But these are the ones you and I will use. And what the platforms take. So let's look under the hood.
This is an example of the SRT file. It has sequence numbers. So it will appear in order. The captions appear first, second, third.
One, two, three, four, five. After each sequence number is the time code. The first time code is when the captions show up. Followed by the second time code -- that's when the captions go away.
And then the caption appears after the time code. Very simple. SRT is like the most basic. VTT is basically SRT on steroids.
So it is based off SRT, but takes it to another level. Just like HTML uses CSS to be more for adding color and positioning and all that stuff. Anyway, WebVTT has "webvtt" at the top of the file, and then time caption, and language English. Now, WebVTT does not have the sequence number. It's optional.
It will work with them and it will work without them. Personally, I like they don't have them. It makes it cleaner and easier to read. And then it's followed by the time code.
Start of the captions. End of the captions. And then the captions. The time code is different by one thing.
The milliseconds -- there's a comma in the SRT. It has the comma. And the VTT has a period. which I find more readable.
And now the one thing VTT can be useful for is positioning. So if you have an on-screen text or something at the bottom, where captions typically appear, you can send the captions up top, temporarily. So you can see both. It's very important to make it easy for people to see both.
Don't make them strain or turn off the captions to see what's behind it. So I'm gonna show you a video. Very short. That will describe ... (quieter) what's going on.
Oh, whoops.
This is a screen shot. My bad. I thought we had video in here. Oh, whatever.
Oh, it is a screenshot. Because, as you see, my name is on the bottom. And at the top is the caption. And the way I made that happen is simply adding line:0 right after the second time code.
Time to wrap up with recommendations. Now we're gonna talk about why line length and line division matter. So here are two side-by-side videos of me. One has edited captions.
Accurate edited captions. The other has automatic captions. Based on... ... it did the line breaks.
I did not touch the line breaks. I did not touch the line division. I did not touch anything. The only thing I touched was to make it accurate.
Because if you have it inaccurate, it makes it very hard to see the difference. So I'm going to play the video. Again, there are two videos, playing at the same time. If you want to look away.
MERYL: So a good example of how you don't want to break things. For example, W3C and WCAG should be next to each other. Because it's part of that. When you split it up, it kind of affects the cognitive understanding of it.
And then you don't want to split up a person's first and last name. You don't want "Meryl" on the first line and "Evans" at the start of the second line. They need to stay together. Those are just simple examples.
Captioning Key has an excellent guide on line division. And we will provide that resource at the end. And now...
THOMAS: All right. And so another piece that we're gonna just be promoting is this ability to add custom vocabulary. Obviously personalization in an AI engine potentially costs money. But as we showed in our first test case, depending on where we work and the language we use and the acronyms and proper nouns in our life, we're going to have custom vocabulary.
So this is something that exists in some software. Such as Dragon Naturally Speaking and Descript. So one recommendation or thing to advocate for, I believe, in the future, is for these mainstream solutions like YouTube, Vimeo, Whisper, to have this capability. Because as we showed, it's not going to be able to work in a general sense.
It is going to be more specific to the areas that we work. It's going to have to be that way.
MERYL: So our recommendation is: Make progress in creating high-quality captions. As I always say and y'all know I say a lot progress over perfection. And I'm wearing the shirt to back it up. And it has the Accessibility in the O.
So when I say progress, I say step one, add captions. Step two, make sure they're accurate. That's making progress. We don't expect perfection on the first try.
And then review and edit automatic captions and make it part of your work flow. So when you create a workflow for creating videos, you want to make sure that you check the captions for accuracy. And then I would like for all of us to contact AI captioning services, to encourage them to think about programming caption length and line division, and as Thomas said, give us a way to add custom vocabulary. We know it's doable, because there are some services that do it.
And then finally, contact companies that have no captions, and ask for them. Once in a while, I'll see a video on Twitter that I'm like... It should be captioned! And I'll say to the company -- nicely I'll tell them about it.
They don't think about it. We have to remember: We live and breathe accessibility every day. Companies don't. Or the people putting out the video.
The marketing team doesn't. Or whoever. So if you ask nicely, they have come through. And also I mentioned ... With YouTube, that one needs a little different approach. Because they've got to fix the sentences, the capitalization, the punctuation, and the roll-up.
So I contacted YouTube -- Google owns YouTube. So I contacted Google Accessibility. And they wrote right back. It was amazing!
And they asked me a few follow-up questions, and I replied. And they said: They don't know when they'll get back to me. But if I don't have any more follow-up questions, they were gonna send it to the next team to review it. So I have a link to how you can contact Google Accessibility.
It's easy. Yeah ... And ... [emphasizes] And...
I made it easy for y'all! Copy and paste. So you can just copy and paste it. And send it off.
After all, the more people who speak up about it, the more they'll realize: We have a need for this! So take us to the finish line, Thomas!
THOMAS: Yay! All right. And I really want to highlight this as the last point, because part of our work is trying to figure out how to be practical and make results. I really wanted to share what Netflix does.
It's a really interesting thing to learn from, for captioning quality. So Netflix has high captioning standards. That happened related to lawsuits and advocacy and things. But now Netflix has created a model to have high captioning standards across a lot of different languages.
And I think maybe the main takeaway that I have, that I think you can apply in your organization, if you're doing any type of long form video content...
MERYL: One thing. What I remember about the article from Netflix is: They said captions are a primary asset. Not a secondary. But they even admitted...
they treated it as a secondary, once upon a time.
THOMAS: And from a process point of view, what I like is they basically... Let's say 2 to 3 minutes. They call it a few minutes. But the idea is: A Netflix piece of content probably could range from 20 minutes to 2.5 hours.
The process is: Pick a random 2 to 3 minutes. Check the quality of the captions in the language. If those 2 to 3 minutes don't meet the criteria, you kick it back. And then the next time it comes back, pick a different 2 to 3 minutes.
So you're having a process where I don't think it's reasonable to expect to watch the entire video for every piece of content. So I like this idea that if you sort of randomly put that into the process, it's a way to improve the quality, and maybe if you're working with a vendor that's supplying the captions, you can say: Look. Here's how we work. Netflix works this way.
If you don't have great captions in the 3 minutes we check, we kick it back to you. When you get it back to us, we're gonna check a different 3 minutes. It's got to be good. So I think that's, business-wise, a smart way to work.
So I just wanted to make sure we highlighted that. I think you could really use that in your organizations, if you work with a lot of multimedia content. Because a lot of people are gonna push back to watching hours and hours of content. So this is more practical.
And do you care? I put this in there. Because you know, I think I... I think this is just so important, from everything we do in accessibility.
But as we said, we would like to ask people: Advocate and push for these changes. I think... You know, Meryl was saying: YouTube's had lowercase and no punctuation, for many years. So for quality captioning, I think for us to get these improved, you do have to make your voice heard and send in feedback.
So we want to really always push that with our Meetup. And encourage everyone. We'll try to make that easy too, for people. But really want you to note that it's obviously not good enough now.
And like we said, at MJ, our experience is definitely not good enough. So... Push for change! We have a link to the resources.
And again, we'll send this out on the Meetup page, and on LinkedIn. And I think now we just want to say thank you very much. I know... (applause) Thank you.
I know we are kind of close... We're already over, a little bit, on time. But we can take a few questions.
How did you choose the tools you were gonna test, and did you only test free tools?
THOMAS: We did not only test free tools. So the question was: How do we choose the tools that we were going to test? We basically -- we're trying to find tools that we can work with an API. Because, you know, we wanted to develop it and make it coded.
Whisper was manual. For what we did. And we only did that, because of the attention to OpenAI. But with Vimeo, YouTube, and Azure, we could automate it.
So that way, we could keep this going. So... This is for us the beginning of the process. And we'll hopefully be able to try it more.
Sorry if this is an off-topic question, but something I've spent a lot of time struggling with is trying to get different platforms to kind of use a screen reader to read captions out loud. To me, it's usually foreign language and so on. But I was just wondering... And it seems like it's very inconsistent, and a few places will let you do it, and it's very hard to find the settings, et cetera, et cetera.
I wonder if you know anything about that, if there's any discussion of that, or if that's not really something that anyone's aware of. I'm not sure.
THOMAS: I don't have a lot of details on that functionality. I know there are screen readers that will read the captions in one language, but I'm not sure about other languages.
MERYL: I'm not sure I heard the question correctly. So I know for a fact that refreshable Braille readers can read the captions on YouTube. There's a transcript. But, for example, Zoom has transcripts that are not compatible with that.
So we need to see more things -- that's the one thing YouTube does very well. Screen readers are not compatible with basic captions. They basically need the transcript. So there's a lot of work that needs to be done.
JOLY: There were two platforms I was surprised you didn't go for, and one was Facebook. Which I use quite a lot, on livestream. And my mind has gone blank on what the other one was. Well, Web Captioner, which uses Google Translate.
And it was interesting. If you actually look at... I've compared YouTube Live Captions to YouTube Encoded Captions, and they're two different things. Because I think it's closer.
But what I thought about... Wondered about... Is how much it's possible to crowdsource corrections on captions. I know there was...
What's it called? Amara? I forget the name. But they do the TED Talk things.
But if there isn't a system... It used to be that... Didn't CAPTCHA help with optical recognition, because every time you did a CAPTCHA, you assisted the optical VR? So couldn't you get everybody to correct captions for a repetitive task to get from A to B or something like that?
Or voluntarily do a minute a day or three minutes a day?
THOMAS: I would just say... I think that's all great points. Part of us doing this is... All these ideas, I think, more needs to happen.
And I think we do have even the ability -- I think already with a11ynewyork... I said "alley" New York. A-eleven-y New York. Accessibility New York.
I think we have a way to submit, but we don't actually have a workflow or process for that. So it's actually a great point. I think that's something that is a big opportunity. How do you crowdsource it, or say...
Well, three people said change this. Or... Instead of one person said change this. Those things might exist.
I'm not aware of them in the moment. I think that's definitely an opportunity.
So this might actually be a better question for the next Meetup. But with generative AI being the topic du jour... Will the text to video platforms come with captioning in the videos? Or is that something that's a great unknown right now?
THOMAS: Text to video platforms? What do you mean, specifically?
So the way that DALL-E creates images from text, in the next few months, or maybe in the next year, there'll be platforms where you can put in text, and a video will be produced. So have you heard of anything about... You know, if those videos will come captioned, or... You know, thought about for accessibility at all?
THOMAS: Yeah. Have not seen that. But it does make sense that you can integrate in the... I think there are some start-ups that are doing these mash-ups, using the APIs to do things like that.
But... I don't think it's... As far as I know, not built into the platform now. But it should be.
And at least... Again, maybe it's not gonna be worthwhile, if you take the images that we showed at the top. You know, the alt text for that. You're like...
Well, that shouldn't have been the image that we used anyway! Yes. And video will have several images. So...
It's questionable. But I think it's definitely something that should be looked at and considered.
I'm gonna guess they're gonna do moving video at first that's silent, and then the talkies will come later. (laughter)
It seems like a lot of the testing you did -- where the system has time to process and kind of come up with the captioning. And I'm wondering if you noticed any quality difference between, like, YouTube versus Google Meet, where it's doing the live captioning on the spot.
THOMAS: I do think that... As Joly mentioned, there's definitely different APIs being used between the YouTube transcription and Google Meet. So if you look at the comparison... But we didn't do that as part of this work.
But it is definitely not the same. From what we see.
MERYL: I was asking the same thing. Because I have a connection at Google. And Google captions on the Android have way better captions than YouTube. And guess what?
YouTube comes under Google as well. But somebody made an excellent point. So millions and millions of minutes of video on YouTube. Chrome is on a per-user basis.
They may not have it on all the time. So it's not always video. And the same thing with the phone. It's only captioning this one thing in my hand.
Not for everybody in the world. So I see where it can be a mismatch. And plus... YouTube was not always owned by Google.
So it is a mammoth of a company. And sometimes making change takes time.
THOMAS: And I'll just add one other quick observation. Just the literal timing between phonemes of speaking words and having the people with different... You know, English as a second language... I could see just from the tests we did...
Little extra spaces in time, which don't seem like a lot, listening, but in the coded system, it seemed to make a big difference. Like, the more time was put between the phoneme, it was more likely to be another word. And again, I think that goes to whatever it's trained on. It's a model that doesn't have all of those considerations.
But we did sort of observe that.
MERYL: And talking about translation -- you know, I aim for 32. Okay. Every time I get 32. Sometimes I get 34.
It doesn't match. But the reason I keep them short -- for a lot of reasons. If you're translating to a different language, the other language might be really long. Because I remember when I did my TED Talk, and Makoto in Japan, a journalist created a Japanese version of a video I wanted, and I was shocked at how big the captions were and how long they were, because the Japanese language was different from the English language.
And that really taught me something about translation.
I was bummed to hear about your experience at the theater. And I'm wondering... The company that you used -- was that the in-house one that every theater offers? Or was that an external service?
MERYL: No, it was GalaPro. Which all the theaters use. It's from the Schubert Organization. So...
I think there's a couple of shows that don't even use GalaPro. Because I was trying to find out about it. And they didn't show up in the GalaPro app. So there are some shows in New York that do have captioning.
And I guess they do something different. But the GalaPro is not theater-specific. It's an app that -- they even use in North Carolina. A colleague of ours uses the GalaPro in North Carolina.
So... It's just up to the theater what they use.
THOMAS: And also, we picked the show we went to from looking at GalaPro. So we were like... Oh! Let's look only at the list of shows that are in this app.
Assuming if it's in the app, it's gonna work. So...
MERYL: And it was a show I had never seen. Didn't know the lyrics. I mean, if I saw Chicago, it would be easy! (laughter)
MERYL: Don't get me started. I'll start dancing! I love All That Jazz. So I tried to pick something...
Even though I'm at work -- Michael Jackson -- it's been a long time I knew a lot of the music. But still, I didn't know the story line. So that didn't go well.
Hi. This is not a question, really. But... For the fact that you mentioned that Netflix uses a process to test...
For the videos, like you see three minutes of it, and randomly check... So... I think we should also... Oh!
MERYL: They're better than GalaPro. So we saw way, way, way more of these options. It was the opposite. It was about the time I saw something on the GalaPro...
Yeah. So... We also are working on unstructured documents. So when you have a problem with screen readers -- right?
To read those unstructured documents, like how Patrick was telling -- maybe not different languages, but at least the Rs and Ns and tables where there are... You know, it doesn't really capture it. So... If I need to test a 60-page document, for a screen reader, whether it really accurately reads it well -- it is a challenge.
So maybe these tips, what you gave, are very useful, I think. We should also incorporate it, and see how it works. Yeah. Thank you.
THOMAS: I agree. I agree. Always trying to figure out: How can you make it not seem so daunting? And put things into the process that people will buy into, in an organization?
And maybe it's easier to get people to buy into that. Might still have the same result. Because you'll find, probably, a problem. If it has problems, you'll find, probably, a problem on three pages out of the 60 pages.
So yeah. I agree.
JOLY: There's some comments on YouTube. Dawn says: Can you do a livestream about captions used in meeting software like WebEx, Google Meet, Zoom, et cetera, next time? Someone says that the YouTube captions -- our YouTube captions look very good. Which is...
Hm. What about automated captions for work meetings? Did you test them? Any thoughts on SubPLY for captioning?
Do you have any information on how to optimize captions for WebEx? Where to find the Netflix article. Would love to learn more. How do we contact Google Accessibility?
What's the link? Can you post it in the chat?
THOMAS: Okay. Let's pause. I am not a machine! Unfortunately, I'm not an AI machine.
But... Yes. We are gonna mostly have the responses to the resources and how to contact in the resources page. That will be shared out on social media.
And was displayed in the QR code in the presentation. Yeah. If this code... If you scan that, that will take you to the web page.
MERYL: If you go to YouTube, click the link, and it'll take you to the other resources we talked about.
THOMAS: And I think we are... We've definitely taken up a lot of the time today. So we will follow up with everyone after this Meetup. We want to again say, though, that all the captions you are seeing on the YouTube stream were human captions from the amazing Mirabai Knight.
Say hi, Mirabai.
CAPTIONER: Hi!
THOMAS: And we also want to say, again, back to the top, thanks to the sponsors. And sorry for this animation. Equal Entry, Google, Internet Society of New York, Joly MacFie, who has been streaming us to YouTube, Asana, Fable, and Evinced. We thank all of these companies for helping us create an accessible Meetup.
We also say thank you to our Sign Language interpreter tonight. For having great Sign Language. We really appreciate that as well.
Calls to Action
- Make progress in creating high-quality captions.
- Including adding, reviewing, and editing automatic captions into your video creation workflow.
- Did you spot a video without captions? Ask for captions.
- Contact AI captioning services about:
- Caption length
- Line division
- Ability to add custom vocabulary
- Contact Google Accessibility: (Fill free to copy and paste the following.) “YouTube automatic captions rarely contain punctuation, sentences, and capitalization at the start of sentences. It makes the captions harder to read and understand. Please add this functionality.”
Resources
- Caption Guide
- Captioned side-by-side videos showing captioning best practices
- Captioning video FAQs
- Captioning Key Guide from DCMP
- Captions: Humans vs. Artificial Intelligence
- Gallaudet research [pdf] shows captions with punctuation lead to a better experience than without them
- Why are Netflix’s Standards for Subtitles and Captions So High?
- Video: Homophones comparison of AI captions (Four videos of Meryl)
- Video: Line length and line division comparison (Two videos of Meryl)
- W3C WAI Captions / Subtitles page
- WebVTT experiments
- Whisper AI transcription and translation page: Here’s how to create a caption file using Whisper.
- Choose “medium”
- Upload video or enter URL of video
- Select “transcript” or “translate” under “Task”
- Select “Submit”
Speaker bios
Thomas Logan is the founder and CEO of Equal Entry, co-founder of A11yNYC and A11yTokyo, and founder of Accessibility Virtual Reality (A11yVR). Connect with Thomas on LinkedIn.
Meryl Evans is an accessibility consultant with Equal Entry, co-organizer of A11yNYC and A11yVR, TEDx speaker, and a LinkedIn Top Voice. Connect with Meryl on LinkedIn and watch her TEDx Talk.
Want to work with us or start a conversation? Contact us.